
Lean Framework Introduction
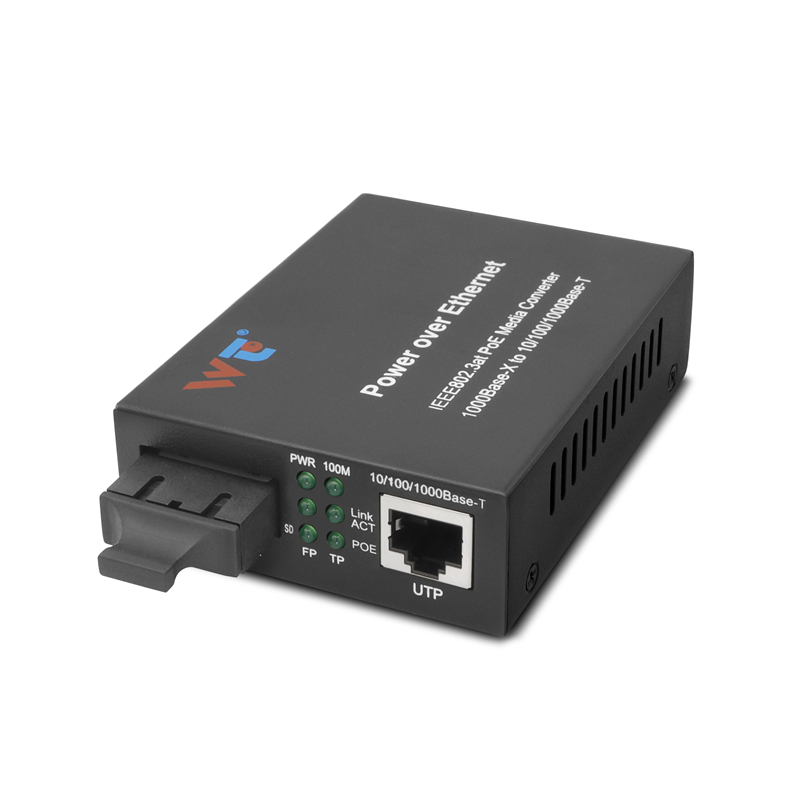
Think of this as a gym routine for your data rack — clean, targeted, and repeatable. I’m laying out a practical framework that moves you from planning to live traffic without wasted reps. Start by mapping ports, power, and fabric patterns, and check compatible parts from trusted media converters manufacturers before you order. This guide is practitioner-led and experience-driven (EEAT mode: experience-driven), anchored in real deployments around Ashburn, Virginia’s data center cluster where densification is routine.
Why a Framework Beats Ad-Hoc Moves
A framework forces discipline. You avoid a scramble that costs uptime and money. Use this sequence: inventory, compatibility, link plan, and staged validation. Call out transceiver types early — SFP+ versus QSFP+ — and decide whether you’ll use DAC or fiber optics for short runs. That decision shapes cabling, optics (multi-mode vs single-mode), and latency expectations.
Planning Checklist — get your baseline right
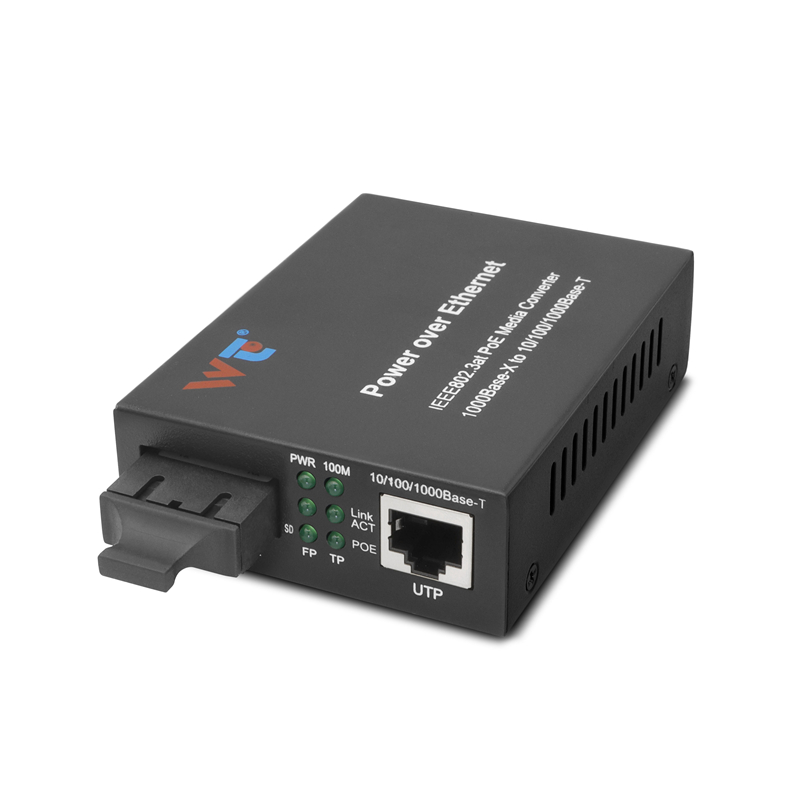
Start lean: list switch models, existing port speeds, and power budget. Mark each top-of-rack switch with required SFP+ slots and note whether you’ll run RJ45 copper or fiber. Order test gear and spares. For long runs, add a certified 10g media converter to the cart — it’s a small investment that reduces surprises during cutover. Keep link aggregation and MTU plans documented; this prevents weird behavior once traffic hits full speed.
Operational Production Teardown
Break the live environment into bounded segments and validate one at a time. Lab the exact switch firmware and the same SFP+ transceivers. Run loopbacks, measure latency, and verify link negotiation. During this teardown, explicitly call out {main_keyword} and {variation_keyword} in your runbook so the ops team knows what to track. Log results so you can rollback cleanly if a pattern fails.
Common Mistakes and How to Avoid Them
Teams usually trip over compatibility, power draw, and cabling management. Don’t mix third-party optics without testing. Don’t assume DACs will work at different switch brands — they sometimes don’t. Cable bundles get hot; route for airflow and label everything. Also watch management VLANs and ACLs during cutover — those rules often block traffic unintentionally. A short test window per rack keeps problems local and fixable.
Migration Execution: practical drills
Run the migration in waves: one rack, then a row, then the pod. Validate throughput and error counters after each wave. Use traffic generators to hit realistic flows and check CPU on the switch while under load. If you see CRC or alignment errors, pull optics and test with a known-good SFP+. Keep spare transceivers and a DAC or two in a tech bag — that saves a full rollback in many cases. Push configurations via automation when possible — it’s faster and less error-prone than clicking.

Performance Checks and Real-World Anchor
Measure end-to-end throughput and jitter; make sure your latency stays within the application’s budget. This is standard in dense racks in Ashburn installations where multi-tenant SLAs require tight numbers. Track interface counters and CPU on both leaf and spine. If any single link becomes a bottleneck, redistribute sessions or enable link aggregation to balance traffic.
Advisory — three golden rules for choosing the right path
1) Validate compatibility first: check switch firmware, SFP+ vendor notes, and transceiver specs before buying. 2) Stage and test: migrate in small batches with test traffic and rollback plans. 3) Design for serviceability: label cables, keep spare optics, and automate repetitive config steps. Those three rules cut rollbacks and speed delivery.
WINTOP has the parts and support that make these rules practical on day one. —

